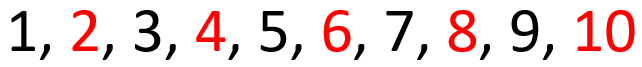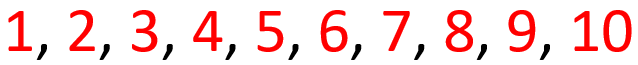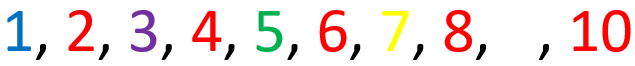Task 1: Introduction
This room is part of a series of rooms that will introduce you to reverse engineering software on Windows. This room will talk about the basics of reverse engineering. In future rooms, we will start doing some reverse engineering and work our way up in difficulty and complexity. This series will focus on analyzing executables, however, keep in mind that reversing is a large field not just covering binary analysis, and not just covering software.
What Is Reverse Engineering?
Reverse engineering is essentially being given a result and figuring out how it got there. That knowledge can be used to find vulnerabilities in the logic and methods used to achieve the result. It starts with finding what you want to attack, then figuring out how it works, then finally doing what you want with it. For security researchers, the goal of reverse engineering is to find where the developers made a mistake or got lazy. For example, developers often think encrypting network traffic is enough, but reverse engineers can get around that encryption. This is why developers shouldn't encrypt the data their software sends to their servers, and then be lazy about sanitizing the data when it hits the server.
It's a Long Road...
Becoming a skilled reverse engineer is quite a long process. Rest assured, once you do develop your skills it's quite fun. No one can teach you everything you need to know about reverse engineering. You're going to constantly see something new and it's going to confuse you. That's the life of a reverse engineer. It's really frustrating for some people, but as a reverse engineer, you're often left to figure it out yourself. You'll constantly be looking up how something works, then tinkering around with it yourself. Keep your head up though, eventually, you can start to use your skills to find vulnerabilities, develop exploits, manipulate processes, and do loads of awesome stuff.
Why is it so hard?
Computers aren't supposed to be human-friendly, they're built to be fast. Think of assembly as a unionization between computer and human languages; Something the computer could understand and perform quickly, while also giving us humans something to understand (opcodes). Over time, however, that's changed. We now almost exclusively write in high-level languages and compilers translate that into computer language. There's a massive difference between compiler-generated assembly and human-written assembly. Compilers use all kinds of crazy techniques that sometimes don't even make sense, but it's for efficiency. Yes, the high-level code was originally written by a human, but the compiler has done away with the human inefficiencies. This is why it can be so hard to reverse engineer software sometimes. On the bright side, eventually, you'll start to think more like the compiler and it won't be as bad. You may even develop the ability to finally write good code!
Tools
This course won't be dependent on any single tool so use what you want. x64dbg, Ghidra, and SysInternals will be provided on the VMs used in future rooms of this series.
Prerequisites (Knowledge and Notes):
- Computer Science Concepts
- You don't need a degree, and some concepts will be covered here. Ultimately it's your understanding of how computers and software work that will lead you to your success or failure.
- C/C++ Experience
- For reverse engineering, experience matters more than knowing advanced C/C++ techniques. Advanced techniques are almost always just abstractions of multiple simpler concepts anyways.
- Assembly (Recommended)
- I will cover the basics. You don't need to know a ton of assembly, but being knowledgeable and comfortable with it will make you significantly better and faster. I will use the Intel syntax because I think it's the easiest to read and it's the default for Windows tools. Note that when working with Linux, AT&T is more commonly used.
Mindset - Feel free to skip this part.
Something to understand is that computers are extremely stupid. They operate with pure logic and they don't make any assumptions.
I will attempt to demonstrate this with a basic "riddle" (admittedly not a hard one).
Let's say you tell the computer to write the numbers 1-10 and make all of the even numbers red.
This is what you might expect:
That looks correct, all even numbers are red just as expected.
The computer may also generate the following:
Once again, the list is valid and follows the rules. All even numbers are red.
If you're confused, don't worry, that means you passed the CAPTCHA. Some people's brains will flip the rule and tell them that all red numbers are even, which is not true according to what we told the computer. Computers won't flip the rules or apply any sort of assumptions like a human might.
In fact, the rules don't dictate anything about the odd numbers, so they can be any color we want!
"Where did the 9 go?", the programmer thought. "The computer must have made an error and forgot to write the 9. Maybe I'm off by one, classic error!" And on the little programmer goes on to waste hours of his life, eventually slamming his head on the desk once he figures out it was colored white.
What is a Protocol?
TCP, UDP, HTTP(s), FTP, and SMTP are all protocols. Protocols are simply templates that are used to specify what data is where. Let's use an example.
01011990JohnDoe/0/123MainSt
Without some sort of guide or template, that just seems like a mess of data. Our brains can pick out some information such as a name and a street. But computers can't do that, and even we can't pick out all of the data. It's confusing because it's all packed together in an attempt to make it as small as possible. Here, let me give you the secret formula:
BIRTHDAY(MMDDYYYY)NAME/NumOfChildren/HomeAddress
Now it makes sense. The collection of numbers at the start is a birthday. Following the birthday is a name. There is then a forward slash and the number of children they have. Then another forward slash and a home address. Here is another example:
03141879AlbertEinstein/3/112MercerSt
That's what a protocol is. It's simply a template that computers can use to pick apart a series of data that would otherwise seem pointless.
I also want to point out the delimiters (the forward slashes) used for the number of children and the street they live on. Because some data has a variable length, it's a good idea to distinguish between them in some way besides a specific number of characters. Remember, a computer can't make assumptions. We need to be very literal or it won't know what we mean. The rules for the protocol are as follows: Assuming the template is filled out correctly, the first 8 characters represent the birth date. The characters following the date up to the forward-slash are the person's name. Then the next character(s) following that forward slash and up to the next forward slash is the number of children that person had. Finally, the rest of the data after the final forward slash is the person's home address.
Answer the questions below
Now that you have been introduced to the way computers think, let's move on to how they work.